
Recap: 昨天跑出了第一次呼叫,但那只是一個python腳本,每次呼叫都要運行
昨天那支腳本是能動,但可是換個問法就要回去改 contents= 那一行
想比較兩種寫法哪個好,得跑兩次然後自己在終端機往上捲
跑完也沒地方留
所以今天把它變成一個端點
在寫分析邏輯之前,先確認 FastAPI 這層是活的
backend/app/main.py:
from fastapi import FastAPI

from app.config import get_settings

app = FastAPI(title="Career Agent Helper", version="0.2.0")


@app.get("/healthz")
def healthz() -> dict:
    s = get_settings()
    return {
        "status": "ok",
        "env": s.app_env,
        "location": s.location,
        "model": s.model,
        "project_configured": bool(s.project_id),
    }
cd backend
uvicorn app.main:app --reload
--reload 只在本機用,改完檔案會自己重啟
開 http://127.0.0.1:8000/docs 就有 Swagger,
之後每加一個端點都會自己出現在上面
不用另外寫測試頁
版本:Python 3.12.10、fastapi 0.141.1、uvicorn 0.52.4
@app.post("/analyze", response_model=AnalyzeResponse)
def analyze_resume(req: AnalyzeRequest) -> AnalyzeResponse:
    try:
        return analyze(req.resume_text, req.job_text, req.prompt)
    except AnalyzerError as e:
        raise HTTPException(status_code=e.status_code, detail=str(e)) from e
main.py 只做路由跟狀態碼轉換,呼叫模型的邏輯放在 services/analyzer.py
中間包一層自己的 AnalyzerError,讓路由層不用認識 SDK 的例外型別
等後面換了執行環境,要改的只有 analyzer
回應裡我多放了兩個欄位,usage 和 elapsed_ms
是我要拿來算帳跟量延遲用的
包成端點之後,呼叫可以想打就打
拿一份虛構履歷打一次
{
  "elapsed_ms": 13708,
  "usage": {
    "prompt_tokens": 258,
    "thought_tokens": 1367,
    "output_tokens": 600,
    "total_tokens": 2225
  }
}
Gemini 2.5 系列預設開啟思考,不設 thinking_budget 就是讓模型自己決定要想多久
types.GenerateContentConfig(
    thinking_config=types.ThinkingConfig(thinking_budget=0)
)
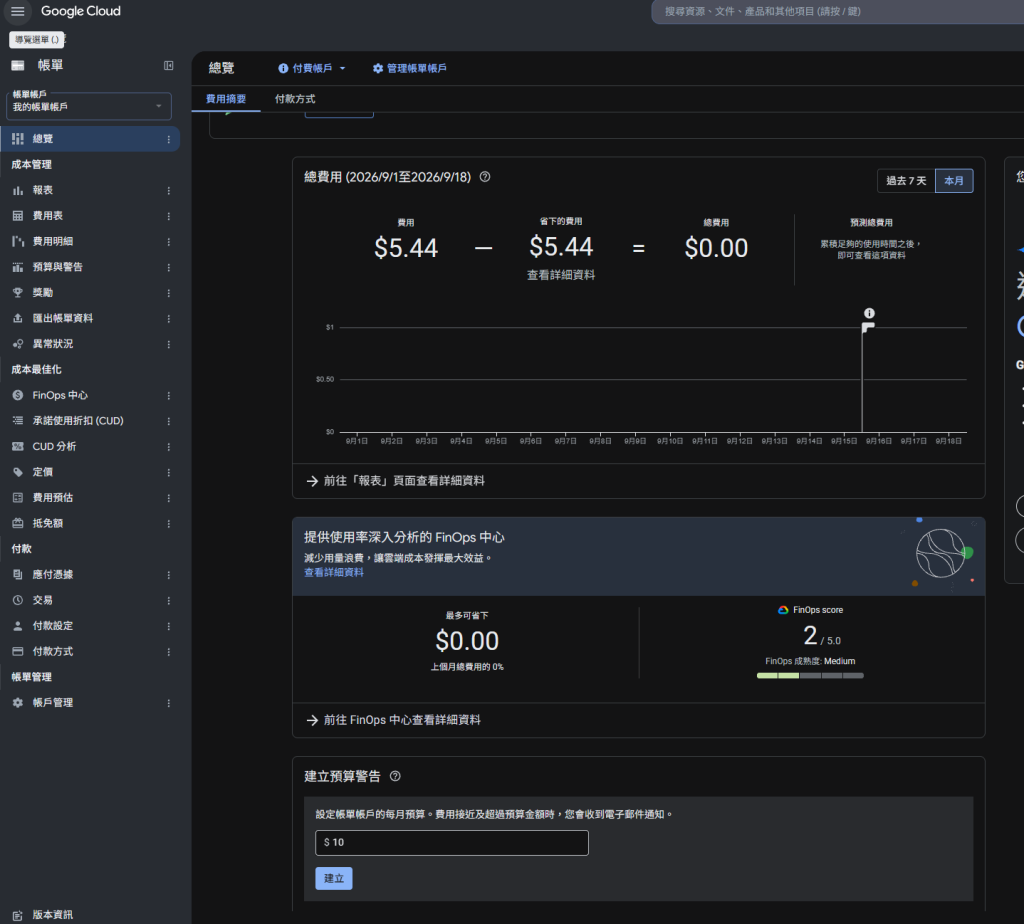
Console 的預算設定有兩種,差別很大
我兩個都設了
上限 $10 防手滑
Github Repo 連結:
https://github.com/kai98k/career-agent-helper
把這個端點接上畫面


 iThome鐵人賽
 看影片追技術