
讀完能做到:寫出三種形態的 function tool(普通函式、long running、agent-as-tool),知道 docstring 怎麼寫才會被 LLM 正確使用,也知道為什麼你的三個工具明明可以平行跑,卻還是一個一個慢慢執行。
前五天我們談的都是 agent 怎麼被定義、怎麼被跑起來。但一個只會生成文字的模型,說穿了就是一台很會接龍的機器——它不會真的幫你查天氣,也不會真的幫你訂機票。讓 agent 從「聊天機器人」變成「真的能做事的助理」的關鍵,是今天的主題:Tool。
官方文件對 Tool 的定義很直白:一個模組化的程式元件「可能是一個 Python 函式、一個類別方法,甚至是另一個 agent」,設計來執行某個明確的預定義任務。它不是模型的一部分,而是外掛給模型的「手腳」。這裡有一個經常被誤解的地方:工具本身沒有推理能力。決定「要不要用這個工具」、「用什麼參數呼叫它」的,永遠是 LLM;工具只負責老老實實執行寫死的邏輯。所以整個系統的智慧,並不是分散在工具裡,而是集中在模型怎麼理解你給它的工具描述。
ADK 把 Agent 使用工具的過程拆成五步:
這五步裡,前兩步完全仰賴你怎麼寫工具——這也是這篇文章接下來大半篇幅都在講「怎麼寫一個好工具」而不是「工具的 API 有哪些參數」的原因。
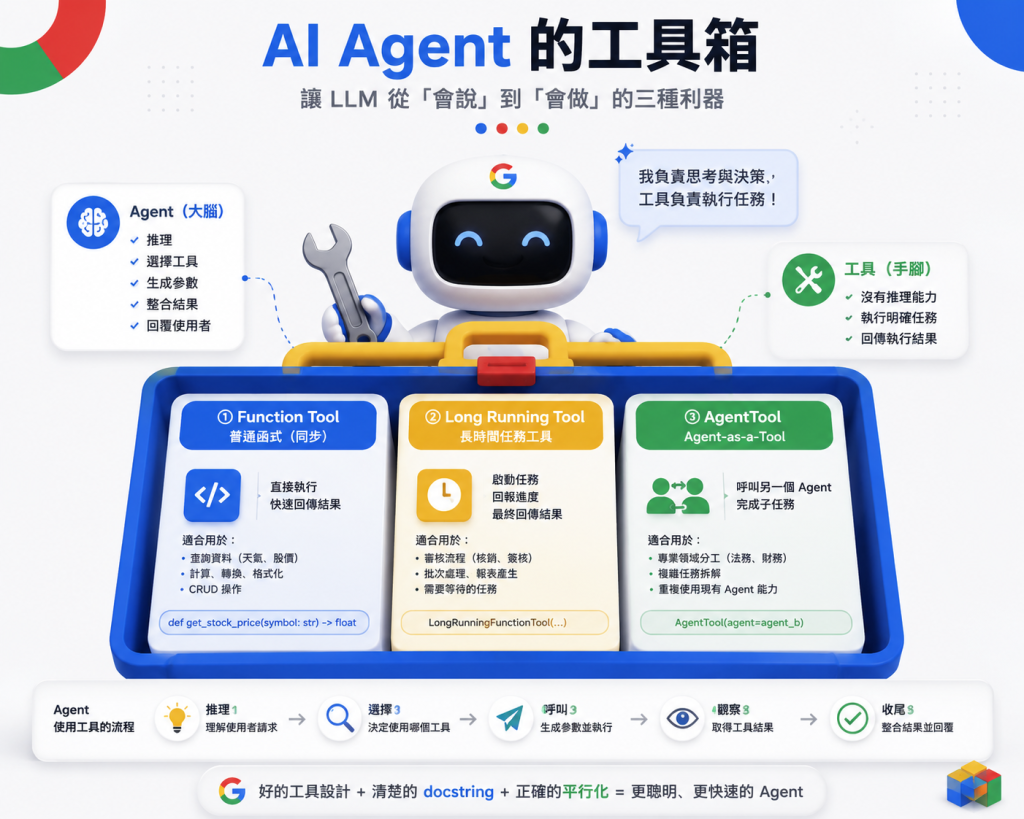
ADK 把工具分成三種:
今天聚焦在 Function Tools,因為它是你會寫最多次的東西。
最基本的形態,就是一個有型別提示與 docstring 的函式,包一層 FunctionTool。官方文件示範的是一支真的會打外部 API 的股票查詢工具(先 pip install yfinance),而不是隨便寫死幾個城市名稱的假邏輯:
import yfinance as yf

def get_stock_price(symbol: str):
    """   <---- 這段就是 docstring ---->
    Retrieves the current stock price for a given symbol.

    Args:
        symbol (str): The stock symbol (e.g., "AAPL", "GOOG").

    Returns:
        float: The current stock price, or None if an error occurs.
    """
    try:
        stock = yf.Ticker(symbol)
        historical_data = stock.history(period="1d")
        if not historical_data.empty:
            current_price = historical_data['Close'].iloc[-1]
            return current_price
        else:
            return None
    except Exception as e:
        print(f"Error retrieving stock price for {symbol}: {e}")
        return None


stock_price_agent = Agent(
    model='gemini-2.0-flash',
    name='stock_agent',
    instruction='You are an agent who retrieves stock prices. If a ticker symbol is provided, fetch the current price. If only a company name is given, first perform a Google search to find the correct ticker symbol before retrieving the stock price. If the provided ticker symbol is invalid or data cannot be retrieved, inform the user that the stock price could not be found.',
    description='This agent specializes in retrieving real-time stock prices. Given a stock ticker symbol (e.g., AAPL, GOOG, MSFT) or the stock name, use the tools and reliable data sources to provide the most up-to-date price.',
    tools=[get_stock_price], # You can add Python functions directly to the tools list; they will be automatically wrapped as FunctionTools.
)
注意這支函式回傳的是 float 或 None,不是 dict——這正好對應到後面「函式簽章的細節」會講的規則:回傳值不是 dict 時,ADK 會自動包成 {'result': 原始值}。
instruction 裡藏的教學重點是明確告訴 agent 怎麼處理「查不到」的情況:只給公司名沒給代號時,先做 Google 搜尋找出代號;代號無效或抓不到資料時,要告訴使用者查不到,而不是放著讓模型自由發揮。這是新手最常踩的坑,不是工具寫錯,是「工具寫對了,但沒教 agent 怎麼用結果」。
有些操作不是幾百毫秒能做完的——報帳需要人簽核、批次運算需要跑幾分鐘。這種情境不該讓 agent 卡住等待,而是用 LongRunningFunctionTool:
from google.adk.tools import LongRunningFunctionTool

def ask_for_approval(purpose: str, amount: float) -> dict:
    """Ask for approval for the reimbursement."""
    return {'status': 'pending', 'approver': 'Sean Zhou', 'purpose': purpose, 'amount': amount, 'ticket-id': 'approval-ticket-1'}

def reimburse(purpose: str, amount: float) -> dict:
    """Reimburse the amount of money to the employee."""
    return {'status': 'ok'}

long_running_tool = LongRunningFunctionTool(func=ask_for_approval)
reimburse 不需要另外包一層——官方範例直接把它跟 long_running_tool 一起放進同一個 agent 的 tools=[reimburse, long_running_tool],ADK 會自動把裸函式包成工具。instruction 裡也明講了先後順序(「If the manager approves, you will call reimburse() to reimburse the amount to the employee」):等 ask_for_approval 收到核准回應,agent 才會接著呼叫 reimburse 真的把錢轉出去。
運作邏輯拆成四步:
FunctionResponse 送回給 LLM,agent 這一輪就先暫停。FunctionResponse 交給 LLM,產生使用者能看懂的訊息。官方有個容易被忽略的警告:Long Running Function Tool 是拿來「啟動與管理」長任務,不是拿來「執行」長任務本身。真正耗時的運算應該丟給獨立的伺服器去跑,工具函式只負責發起跟查詢狀態,不要把真正的重活塞進工具函式裡卡住 event loop。
如果這個 agent workflow 剛好又開了 [[Resume 與 Cancel (暫停與取消)]] 的 Resume 功能,還有一條容易漏掉的規則:回報中繼或最終進度時,一定要帶跟原始請求相同的 invocation_id。
invocation_id 跟任務 id 存在一起,回報進度時原封不動帶回去。AgentTool)把另一個 agent 包成工具,讓一個 agent 呼叫另一個 agent 來完成子任務。這裡有一個非常關鍵、而且會在 Day 17、18 的多 agent 章節反覆用到的區分:
| 控制權 | 使用情境 | |
|---|---|---|
AgentTool |
Agent B 執行完,答案傳回給 Agent A,由 A 統整後回覆使用者。A 繼續掌控對話。 | 把 Agent B 當成一個「有智慧的函式」呼叫 |
| Sub-agent(transfer) | 對話責任完全轉移給 Agent B,A 退出。之後使用者的輸入都由 B 處理。 | 真正的職責交接 |
用法很簡單:
tools=[AgentTool(agent=agent_b)]
AgentTool 還有一個 skip_summarization 參數,設成 True 可以跳過框架預設對子 agent 回應做的 LLM 摘要——如果子 agent 的輸出本身已經是格式化好的最終答案,不需要再讓外層 LLM 重新消化一次,這個開關能省一次模型呼叫。
官方文件用一整節篇幅講「怎麼定義一個有效的工具函式」,核心邏輯是:LLM 只透過函式名稱、參數、型別提示、docstring 來理解這個工具,它看不到你的原始碼實作。所以這幾件事馬虎不得:
get_weather、schedule_meeting),不要用 run、process、do_stuff 這種模糊到連人類都猜不出用途的名字。city: str 這種型別,ADK 靠它生成給 LLM 看的 schema。def my_func(destination: str = "Paris") 這種寫法,如果 destination 其實應該由使用者決定,預設值反而會讓模型漏填。dict(Java 是 Map,TypeScript 是 object)。如果你回傳字串或數字,ADK 會自動包成 {'result': 原始值}。強烈建議附一個 status 鍵(success/error/pending),讓模型清楚知道這次呼叫的結果狀態。tool_context 參數(tool_context 是下面「Context injection」段落會細講的注入機制,這裡先劇透一個地雷)。這個參數是框架在 LLM 決定呼叫之後才注入的,寫進 docstring 只會讓模型困惑「這是不是我該提供的東西」。一個「好」的 docstring 長這樣:
def lookup_order_status(order_id: str) -> dict:
  """Fetches the current status of a customer's order using its ID.

  Use this tool ONLY when a user explicitly asks for the status of
  a specific order and provides the order ID. Do not use it for
  general inquiries.

  Args:
      order_id: The unique identifier of the order to look up.

  Returns:
      A dictionary indicating the outcome.
      On success, status is 'success' and includes an 'order' dictionary.
      On failure, status is 'error' and includes an 'error_message'.
      Example success: {'status': 'success', 'order': {'state': 'shipped', 'tracking_number': '1Z9...'}}
      Example error: {'status': 'error', 'error_message': 'Order ID not found.'}
  """
注意這份 docstring 裡藏了三件事:
這三者缺一,模型的行為就會開始飄——它可能在不該用的時候硬用,也可能拿到回應後不知道怎麼解讀。
再補一個常被忽略的細節:Context injection。如果你想在工具函式裡存取 session state 或控制 agent 後續行為,把 tool_context: ToolContext 加進函式簽章,ADK 會自動注入(參數名可以自訂,重點是型別要對)。這一段留給 Day 12 講 Callbacks 與 Event 時再深入,因為 ToolContext 跟 event 系統的關係比表面上看到的更緊密。
如果工具數量一多,或者你想依使用者權限決定「這個人能看到哪些工具」,就該用 BaseToolset 而不是把所有工具都塞進 tools 列表。它只定義兩個方法:
get_tools(readonly_context)——回傳這次要暴露給 agent 的工具清單。因為拿得到 ReadonlyContext,可以讀 session state,依當下的使用者、權限、情境動態決定要不要給某個工具。close()——資源清理,agent 或 Runner 關閉時呼叫。from google.adk.tools.base_toolset import BaseToolset
class MathToolset(BaseToolset):
async def get_tools(self, readonly_context=None):
return [add_tool, subtract_tool]
async def close(self):
pass
注意這個 import 路徑跟前面三種工具不一樣:BaseToolset 要從 google.adk.tools.base_toolset 這個完整路徑拿,不是從 google.adk.tools 頂層直接 import。
這個「依 context 動態出工具」的能力,值得先記住——Day 28 講企業級安全網時,會回頭用它做「依使用者權限決定可見工具」的權限控管範例,這裡先埋個伏筆。
如果你有三個各要 2 秒的工具,循序跑要 6 秒,平行跑理論上逼近 2 秒。這對「一次要打好幾個外部 API」的場景(比價、多來源查詢、同時發送多個通知)幫助很大。
但這裡有一個容易被忽略的前提:平行執行的門檻是你的工具函式必須用 async def 寫。官方的警告寫得很直接——只要有一個工具用同步阻塞式寫法,就會卡住其他本來可以平行跑的工具,即使那些工具本身完全支援平行。也就是說,一個團隊裡只要有一個人偷懶寫了同步版本的資料庫呼叫,整個平行化的效益就泡湯了。
五種常見場景的非同步寫法:
# HTTP 呼叫
async def get_weather(city: str) -> dict:
    async with aiohttp.ClientSession() as session:
        async with session.get(f"http://api.weather.com/{city}") as response:
            return await response.json()

# 資料庫呼叫
async def query_database(query: str) -> list:
    async with asyncpg.connect("postgresql://...") as conn:
        return await conn.fetch(query)

# 長迴圈中定期讓出控制權
async def process_data(data: list) -> dict:
    results = []
    for i, item in enumerate(data):
        processed = await process_item(item)
        results.append(processed)
        if i % 100 == 0:
            await asyncio.sleep(0)  # Yield control
    return {"results": results}

# 密集運算丟進 thread pool
async def cpu_intensive_tool(data: list) -> dict:
    loop = asyncio.get_event_loop()
    with ThreadPoolExecutor() as executor:
        result = await loop.run_in_executor(executor, expensive_computation, data)
    return {"result": result}
還有一件事比程式碼本身更容易被忽略:光把函式改成 async 還不夠,prompt 與工具描述也要寫成「暗示可以平行呼叫」的樣子,模型才會真的一次發出多個工具呼叫,而不是規規矩矩一個一個問。官方給的 prompt 範例:
When users ask for multiple pieces of information, always call functions in
parallel.

  Examples:
  - "Get weather for London and currency rate USD to EUR" → Call both functions
    simultaneously
  - "Compare cities A and B" → Call get_weather, get_population, get_distance in
    parallel
也可以直接寫進工具的 docstring,例如「This function is optimized for parallel execution - call multiple times for different cities.」——這句話看起來只是說明文字,實際上是在訓練模型的呼叫習慣。很多人把工具改成 async 之後,發現實際延遲沒有改善多少,回頭一查,問題往往不在程式碼,而在 prompt 完全沒暗示模型可以一次多發幾個呼叫。
這是最容易在專案中期才踩到、而且踩到會很痛的坑:Code Execution、Google Search、Agent Search 這三個內建工具,不能跟其他任何工具(包括彼此)共存在同一個 agent 裡。
root_agent = Agent(
    name="RootAgent",
    model="gemini-flash-latest",
    tools=[custom_function],
    code_executor=BuiltInCodeExecutor() # <-- NOT supported when used with tools
)
這行程式碼在語法上完全合法,執行時才會出問題——這也是它特別陰險的地方。兩個 workaround:
Workaround 1:把每個內建工具包成獨立 agent,再用 AgentTool 包起來(Python 用 AgentTool(agent=...) 建構子;Java 是 AgentTool.create(...) 靜態方法——官方文件把這個 workaround 的小標題取成 Java 的寫法,純 Python 讀者對照下面的程式碼會發現完全沒有 .create(),不用懷疑自己漏抄):
search_agent = Agent(model='gemini-flash-latest', name='SearchAgent',
                      instruction="You're a specialist in Google Search",
                      tools=[google_search])
coding_agent = Agent(model='gemini-flash-latest', name='CodeAgent',
                      instruction="You're a specialist in Code Execution",
                      code_executor=BuiltInCodeExecutor())
root_agent = Agent(name="RootAgent", model="gemini-flash-latest",
                    tools=[AgentTool(agent=search_agent), AgentTool(agent=coding_agent)])
Workaround 2:bypass_multi_tools_limit=True——僅 ADK Python 對 GoogleSearchTool 與 VertexAiSearchTool 提供的內建繞道。
技術細節:
另外還有一條容易漏看的規則——內建工具不能用在 sub-agent 裡(上面提到的兩個 Python 例外除外)。如果你的架構是「root agent 底下掛一堆 sub-agent,其中一個 sub-agent 想用 Google Search」,這條路直接不通,得改用 AgentTool 的模式。
今天講完了「自己寫工具」的完整脈絡:三種形態、docstring 怎麼寫才有效、平行化的隱藏前提、內建工具的共存限制。明天從「自己寫」跳到「用開放協定接別人寫好的工具」——Model Context Protocol,以及 ADK 怎麼同時當 MCP 的客戶端與伺服器。
Google ADK 官方網站
GitHub - Agent Development Kit (ADK) 2.0
GitHub 開源實作:https://github.com/SeanLinH/adk_tutor
下一章 Day 07 - 開放協定:MCP 與 OpenAPI 整合


 iThome鐵人賽
 看影片追技術