

試想,你買了一支最新的智慧型手機,發現它有一個很方便的功能:臉部辨識(Face ID)。可是,有人拿出 20 年前的摺疊手機,告訴你:「以前的手機根本沒有臉部辨識,所以這個功能一定不重要!」你一定會覺得這個結論很奇怪。
一項功能在過去不存在,不代表它在今天沒有價值。 但反過來說,如果某個功能經過很多代更新,始終被保留下來,例如基本的通訊功能,那麼它可能真的非常重要。
科學家研究 DNA 時,也會遇到類似的問題。有些序列在人類、黑猩猩、老鼠等不同物種身上都很相似,這可能表示它們受到演化限制;另一些調控功能可能較新,或僅在某些細胞情境下發揮作用,只看物種之間的相似程度,就可能漏掉重要線索。
所以今天我們請來兩位偵探:
第一位研究「過去」:演化保守性。第二位研究「可能發生什麼」:分子功能預測。
有時兩位偵探的線索相同,有時看起來互相矛盾。這些不一致並不是科學研究的失敗,反而可以引導我們想出下一個值得實驗驗證的問題。
人類一套基因組約有三十億個 DNA 字母。只有約 1–2% 的序列直接編碼蛋白質,其餘非編碼序列包含啟動子、增強子、RNA 相關序列,以及目前功能仍不清楚的區域。
我們可以把基因想成工廠:蛋白質編碼區像產品設計圖;啟動子和增強子像生產時間和產量的開關;RNA 剪接像將初稿剪輯成正式使用的說明書。某個鹼基從 A 變成 G,可能對上述過程有所影響,也可能沒有可測量的作用。發現變異不等於證明會生病。
PhyloP 研究的是特定序列位置在跨物種比較中的演化速度:正分可表示相對保守,負分可表示演化加速。PhastCons 則是另一套偏向連續保守區段的評分,量尺及意義不同。比對缺口、參照物種、基因組版本都可能影響解讀。UCSC 的正式說明也特別區分這兩種分數。
所以:保守性高,表示值得研究;保守性低,不代表一定沒有功能。 負的 phyloP 分數也不是「負的致病機率」。
AlphaGenome 類序列模型從 DNA 推測可能的 RNA 剪接、轉錄起始、染色質可及性等分子讀出;不同模態、不同 biosample 可能提供互補線索。這類預測能幫我們提出實驗問題,但不等於模型在活細胞中真的觀察到了這些變化。
AVI 則把多種特徵整合成研究排序分數,其中也包含保守性、AlphaMissense 以及其他基因註解。因此不能說「保守性是舊工具、AVI 完全不靠保守性」。
| 工具/線索 | 主要問題 | 可以提出什麼 | 不能直接說什麼 |
|---|---|---|---|
| PhyloP/PhastCons | 這個位置或區段在演化中受到何種限制? | 值得留意的演化線索 | 高分必致病、低分必無功能 |
| CADD | 綜合各種註解,變異的相對排序為何? | 研究優先次序 | PHRED 25 = 25% 或 99% 患病機率 |
| AlphaGenome | 變異可能改變哪些分子讀出? | 剪接、染色質、表達等待驗假說 | 模型預測即實測機制 |
| AlphaGenome Atlas/AVI | 如何查閱預先計算結果並整理候選? | 多種證據的檢索、排序與解釋 | 在所有資料集與病例都一定優於其他工具 |
作者最初的 Day 03 曾援引 Atlas 預印本中的特定 AUPRC、Top 50 召回率,以及 DNM1 範例的 SHAP 剪接歸因。這些數值屬各自的研究子群體與評測條件,不應從單一表格直接推出所有非編碼變異都有相同效能。本次教學程式不重算這些文獻數字;正式引用前應由作者對照相應圖表和 Methods。
假設變異甲在很多物種中都很少改變,卻沒有明顯的人工剪接差分:可能真正相關的是另一種組織、另一個 RNA 事件,或另一種分子機制;也可能沒有實際影響。變異乙的保守性不突出,但某種細胞情境有大的人工剪接差分:它同樣值得提出獨立驗證,不能僅因不保守就被排除。
重要的是:兩種線索的輸入、單位及參照資料不同,並沒有一個可以直接互減或相加的共同臨床量尺。
很多程式小白最害怕的,是打開空白的 VS Code,完全不知道第一行要打什麼。作者原本在 Day03 提出的方法很實用:先把需求說清楚,讓 Google AI Studio 成為可以捏出介面的「數位黏土」,再反過來拆解 UI 與資料流。
今天不需要從空白編輯器開始,而是先開啟 AI Studio Build 模式,把隨包的 AI_STUDIO_DAY03_PROMPT.txt 貼入。
**你想看到的 MVP 畫面:**左邊有演化線索卡,右邊有分子預測卡,下方列出七筆 chrToy 人工變異,能依「兩者皆有訊號/只有一側/缺值」篩選。點開卡片,畫面會詢問「需要什麼額外證據?」
請把 UI 中的數字和資料來源放在旁邊,不要只顯示一個紅色的「危險」標籤。把 null 清楚標成缺值,也不要偷偷把人工分數變成「診斷」。
注意: AI Studio 生成的是前端原型,建立它的過程會使用 AI Studio 的生成服務;不等於這個產物已接上真正的 AlphaGenome API,更不等於 Python 後端、研究驗證或臨床系統已完成。等進入 Code 分頁,再看看 React 的資料陣列、元件與篩選是如何構成的。
| AI Studio 裡看見的元件 | Python 今天要做的事 |
|---|---|
個案卡片 chrToy:100:A>G |
讀取 JSON Fixture,核對欄位與格式 |
| 保守性與分子代理數值 | 檢查數值範圍、正負號、缺值 |
| 「兩位偵探」的分類標籤 | 根據明示人工教學閾值分類 |
| 按鈕切換不同候選 | 匯出 HTML 前端篩選與 CSV 表格 |
| 頁面中的科學限制 | 一併輸出 JSON 與研究問題卡 |
| 可重現性 | 檔案 SHA-256 manifest;不冒充數位簽章 |
本例所有資料都使用 chrToy,並明確標記為 TOY_NOT_GRCH38。其中 toy_phyloP_like 只模仿 PhyloP 的正負號概念;toy_splicing_delta 是作者人為設定的 ALT−REF 代理差分,不是 UCSC、CADD 或 AlphaGenome 的模型輸出。
| 人工變異 | Toy phyloP-like | Toy Splicing Δ | 教學觀察 |
|---|---|---|---|
chrToy:100:A>G |
+3.10 | +0.04 | 只有演化線索突出 |
chrToy:101:C>T |
+0.10 | −0.42 | 只有人工分子線索突出 |
chrToy:102:G>C |
+2.80 | +0.37 | 兩種線索都突出 |
chrToy:103:T>A |
+0.20 | +0.02 | 兩種線索都不突出;不能判定良性 |
chrToy:104:A>C |
null |
+0.33 | 保守性資料缺失 |
chrToy:105:C>G |
−2.40 | +0.03 | 示範演化加速概念;不是不重要 |
chrToy:106:G>A |
+2.50 | null |
分子資料缺失 |
本例只為練習使用 toy_phyloP_like >= +2、toy_phyloP_like <= −2 以及 abs(toy_splicing_delta) >= 0.25 作顯示分類。這三個門檻是教學中人為設定,不是任何官方、臨床或統計顯著性閾值。
將下列程式存成 day03_offline_two_lenses_lab.py。另將隨包的 day03_synthetic_two_lenses.json 放在同一目錄。Python 3.12 標準函式庫即可完成,不必安裝 SDK、申請 API Key 或下載病患基因檔。
"""Day 03: synthetic conservation-vs-molecular-lens teaching demo.

Python 3.12+ standard library only. No API clients, networking, personal data,
patient-level inference, real phyloP calculation, or AlphaGenome predictions.
"""
from __future__ import annotations

import argparse
import csv
import hashlib
import html
import io
import json
import math
import re
from collections import Counter
from pathlib import Path
from typing import Any

DATA_KIND = "SYNTHETIC_EDUCATIONAL_DEMO"
GENOME_BUILD = "TOY_NOT_GRCH38"
DATASET_ID = "DAY03_TWO_COMPLEMENTARY_LENSES_V1"
VARIANT_RE = re.compile(r"^chrToy:([1-9][0-9]*):([ACGT])>([ACGT])$")
OUTPUT_FILES = (
    "day03_two_lenses_report.json",
    "day03_two_lenses_table.csv",
    "day03_two_lenses_matrix.svg",
    "day03_two_lenses_dashboard.html",
    "day03_review_questions.md",
)
CLASS_LABELS = {
    "BOTH_SUGGESTIVE": "雙線索皆突出",
    "CONSERVATION_ONLY": "只有演化保守訊號突出",
    "MOLECULAR_ONLY": "只有人工分子訊號突出",
    "NEITHER_TOY_SIGNAL": "兩種人工訊號皆不突出",
    "ACCELERATION_FLAG": "負向 phyloP-like(示意加速)",
    "INCOMPLETE_EVIDENCE": "證據缺失:不可補零",
}
FOLLOW_UP = {
    "BOTH_SUGGESTIVE": "兩種線索是否指向相同基因與組織?用獨立實驗核對。",
    "CONSERVATION_ONLY": "是否另有非剪接的分子作用?先核對組織與其他模態。",
    "MOLECULAR_ONLY": "該組織的分子變化是否能由獨立 RNA/功能實驗重現?",
    "NEITHER_TOY_SIGNAL": "是否有資料覆蓋與模態限制?不能據此判定良性。",
    "ACCELERATION_FLAG": "確認真實跨物種比對品質與演化加速的解釋,不能推定無功能。",
    "INCOMPLETE_EVIDENCE": "先釐清缺值原因、資料來源與需要追加的分析。",
}
CSV_COLUMNS = (
    "variant_id", "toy_phyloP_like", "toy_splicing_delta",
    "biosample", "evidence_class", "conservation_signal",
    "molecular_signal", "evidence_status", "next_research_question",
)


def sha256_bytes(content: bytes) -> str:
    return hashlib.sha256(content).hexdigest()


def sha256_file(path: Path) -> str:
    return sha256_bytes(path.read_bytes())


def number_or_none(value: Any, *, name: str, minimum: float, maximum: float) -> float | None:
    if value is None:
        return None
    if type(value) not in (int, float) or not math.isfinite(value):
        raise ValueError(f"{name} must be a finite number or null")
    if not minimum <= value <= maximum:
        raise ValueError(f"{name} is outside the toy educational range")
    return float(value)


def validate_fixture(data: Any) -> dict[str, Any]:
    if type(data) is not dict:
        raise ValueError("Fixture must be a JSON object")
    required = {"data_kind", "genome_build", "dataset_id", "dataset_note", "teaching_thresholds", "variants"}
    if set(data) != required:
        raise ValueError("Fixture keys must match the documented teaching schema")
    if data["data_kind"] != DATA_KIND or data["genome_build"] != GENOME_BUILD:
        raise PermissionError("Only explicitly toy genomic data are allowed")
    if data["dataset_id"] != DATASET_ID:
        raise ValueError("Unknown teaching dataset")
    if not isinstance(data["dataset_note"], str) or not data["dataset_note"].startswith("All coordinates"):
        raise ValueError("Explicit synthetic disclaimer required")
    cfg = data["teaching_thresholds"]
    if type(cfg) is not dict or set(cfg) != {"conservation_positive_min", "acceleration_negative_max", "molecular_abs_delta_min"}:
        raise ValueError("Invalid teaching threshold contract")
    thresholds = {
        "conservation_positive_min": number_or_none(cfg["conservation_positive_min"], name="conservation_positive_min", minimum=0.01, maximum=10.0),
        "acceleration_negative_max": number_or_none(cfg["acceleration_negative_max"], name="acceleration_negative_max", minimum=-10.0, maximum=-0.01),
        "molecular_abs_delta_min": number_or_none(cfg["molecular_abs_delta_min"], name="molecular_abs_delta_min", minimum=0.01, maximum=1.0),
    }
    if any(v is None for v in thresholds.values()):
        raise ValueError("Toy threshold cannot be null")
    variants = data["variants"]
    if not isinstance(variants, list) or not 1 <= len(variants) <= 50:
        raise ValueError("Expected 1-50 synthetic cases")
    normalized = []
    seen = set()
    for v in variants:
        if type(v) is not dict or set(v) != {"variant_id", "toy_phyloP_like", "toy_splicing_delta", "biosample", "teaching_note"}:
            raise ValueError("Invalid synthetic case fields")
        vid = v["variant_id"]
        if not isinstance(vid, str) or not VARIANT_RE.fullmatch(vid):
            raise ValueError("Only chrToy:POS:REF>ALT is allowed")
        m = VARIANT_RE.fullmatch(vid)
        assert m is not None
        if m[2] == m[3] or vid in seen:
            raise ValueError("Duplicate case or unchanged allele")
        seen.add(vid)
        if v["biosample"] != "TOY_NEURON":
            raise ValueError("Only teaching biosample TOY_NEURON supported")
        note = v["teaching_note"]
        if not isinstance(note, str) or not 1 <= len(note) <= 120:
            raise ValueError("Invalid teaching note")
        norm = dict(v)
        norm["toy_phyloP_like"] = number_or_none(v["toy_phyloP_like"], name="toy_phyloP_like", minimum=-10.0, maximum=10.0)
        norm["toy_splicing_delta"] = number_or_none(v["toy_splicing_delta"], name="toy_splicing_delta", minimum=-1.0, maximum=1.0)
        normalized.append(norm)
    return {**data, "teaching_thresholds": thresholds, "variants": normalized}


def classify(record: dict[str, Any], cfg: dict[str, float]) -> dict[str, Any]:
    cons, mol = record["toy_phyloP_like"], record["toy_splicing_delta"]
    if cons is None or mol is None:
        code = "INCOMPLETE_EVIDENCE"
        cs = None if cons is None else cons >= cfg["conservation_positive_min"]
        ms = None if mol is None else abs(mol) >= cfg["molecular_abs_delta_min"]
    elif cons <= cfg["acceleration_negative_max"]:
        code, cs, ms = "ACCELERATION_FLAG", False, abs(mol) >= cfg["molecular_abs_delta_min"]
    else:
        cs, ms = cons >= cfg["conservation_positive_min"], abs(mol) >= cfg["molecular_abs_delta_min"]
        code = ("BOTH_SUGGESTIVE" if cs and ms else
                "CONSERVATION_ONLY" if cs else
                "MOLECULAR_ONLY" if ms else "NEITHER_TOY_SIGNAL")
    return {
        "variant_id": record["variant_id"],
        "toy_phyloP_like": cons,
        "toy_splicing_delta": mol,
        "biosample": record["biosample"],
        "teaching_note": record["teaching_note"],
        "evidence_class": code,
        "class_label": CLASS_LABELS[code],
        "conservation_signal": cs,
        "molecular_signal": ms,
        "evidence_status": "SYNTHETIC_UNVALIDATED",
        "next_research_question": FOLLOW_UP[code],
        "manual_review": "REQUIRED",
    }


def build_report(data: dict[str, Any], *, fixture_name: str, fixture_sha256: str) -> dict[str, Any]:
    norm = validate_fixture(data)
    records = [classify(v, norm["teaching_thresholds"]) for v in norm["variants"]]
    counts = Counter(r["evidence_class"] for r in records)
    return {
        "status": "PASS",
        "mode": "OFFLINE_ONLY",
        "data_kind": DATA_KIND,
        "genome_build": GENOME_BUILD,
        "fixture_name": fixture_name,
        "fixture_sha256": fixture_sha256,
        "source_label": "ARTIFICIAL_PHYLOP_LIKE_AND_SPLICE_DELTA",
        "teaching_thresholds": norm["teaching_thresholds"],
        "thresholds_are_official": False,
        "variant_count": len(records),
        "classification_counts": dict(sorted(counts.items())),
        "missing_conservation_count": sum(v["toy_phyloP_like"] is None for v in records),
        "missing_molecular_count": sum(v["toy_splicing_delta"] is None for v in records),
        "case_rows": records,
        "model_prediction": False,
        "clinical_inference": False,
        "real_api_calls_this_run": 0,
        "limitations": [
            "Scores and coordinates are entirely artificial and not calibrated phyloP or AlphaGenome outputs.",
            "Demo cutoffs are arbitrarily chosen for pedagogy, not validated thresholds.",
            "Evolutionary constraint and predicted molecular effect answer different research questions.",
            "Discordance is a follow-up question, not a pathogenicity conclusion.",
            "Missing values are JSON null and never imputed to 0.0.",
            "No patient data, wet-lab experiment, or clinical decision was involved.",
        ],
    }


def dumps_json(obj: Any) -> bytes:
    return (json.dumps(obj, ensure_ascii=False, indent=2, sort_keys=True, allow_nan=False) + "\n").encode("utf-8")


def csv_bytes(rows: list[dict[str, Any]], cols: tuple[str, ...]) -> bytes:
    b = io.StringIO(newline="")
    writer = csv.writer(b, lineterminator="\n")
    writer.writerow(cols)
    for row in rows:
        vals = [row.get(c) for c in cols]
        writer.writerow(["" if v is None else "true" if v is True else "false" if v is False else v for v in vals])
    return b.getvalue().encode("utf-8")


def draw_svg(report: dict[str, Any]) -> bytes:
    """Generate editable 1920x1080 teaching figure, not a biological plot."""
    esc = html.escape
    colors = {
        "CONSERVATION_ONLY": ("#E8DDD7", "#7E5A56"),
        "MOLECULAR_ONLY": ("#DCEBED", "#347D87"),
        "BOTH_SUGGESTIVE": ("#E4E2F3", "#6B62A8"),
        "NEITHER_TOY_SIGNAL": ("#E5E5E5", "#555E65"),
        "INCOMPLETE_EVIDENCE": ("#F5E6CA", "#95702E"),
        "ACCELERATION_FLAG": ("#EBDCE9", "#825D80"),
    }
    rows = report["case_rows"]
    parts = [
        '<svg xmlns="http://www.w3.org/2000/svg" width="1920" height="1080" viewBox="0 0 1920 1080" role="img" aria-label="Synthetic Day03 conservation versus molecular evidence cards">',
        '<rect width="1920" height="1080" fill="#E5DEDA"/>',
        '<rect x="44" y="42" width="1832" height="950" rx="35" fill="#FFFFFF" fill-opacity=".53"/>',
        '<text x="100" y="128" font-family="DejaVu Sans, Arial" font-size="57" font-weight="700" fill="#38414A">Two lenses. Different questions.</text>',
        '<text x="102" y="184" font-family="DejaVu Sans, Arial" font-size="26" fill="#687179">Day 03  |  Evolutionary constraint  ×  Molecular prediction</text>',
        '<rect x="1400" y="102" width="360" height="55" rx="24" fill="#F4E9E3"/>',
        '<text x="1426" y="139" font-family="DejaVu Sans,Arial" font-size="23" font-weight="700" fill="#825D69">SYNTHETIC ONLY  /  NO API</text>',
    ]
    def box(x:int,y:int,w:int,h:int,code:str,title:str,case:dict[str,Any]):
        bg,fc=colors[code]
        a = case["toy_phyloP_like"]
        b = case["toy_splicing_delta"]
        val_a = "NULL" if a is None else f"{a:+.2f}"
        val_b = "NULL" if b is None else f"{b:+.2f}"
        vid=esc(case["variant_id"])
        parts.extend([
            f'<rect x="{x}" y="{y}" width="{w}" height="{h}" rx="29" fill="{bg}" fill-opacity=".91"/>',
            f'<rect x="{x+22}" y="{y+25}" width="10" height="{h-50}" rx="5" fill="{fc}"/>',
            f'<text x="{x+60}" y="{y+53}" font-family="DejaVu Sans,Arial" font-size="25" font-weight="700" fill="{fc}">{esc(title)}</text>',
            f'<text x="{x+60}" y="{y+93}" font-family="DejaVu Sans,Arial" font-size="23" fill="#3D4751">{vid}</text>',
            f'<text x="{x+60}" y="{y+144}" font-family="DejaVu Sans,Arial" font-size="23" fill="#45505A">phyloP-like  {val_a}</text>',
            f'<text x="{x+60}" y="{y+181}" font-family="DejaVu Sans,Arial" font-size="23" fill="#45505A">splice Δ       {val_b}</text>',
        ])
    look: dict[str, dict[str, Any]] = {}
    for record in rows:
        look.setdefault(record["evidence_class"], record)
    pos=[(105,237),(962,237),(105,484),(962,484),(105,731),(695,731),(1285,731)]
    specs=[
        ("BOTH_SUGGESTIVE", "01 / BOTH SIGNALS"),
        ("CONSERVATION_ONLY", "02 / EVOLUTION ONLY"),
        ("MOLECULAR_ONLY", "03 / MOLECULAR ONLY"),
        ("NEITHER_TOY_SIGNAL", "04 / NEITHER IN TOY"),
        ("INCOMPLETE_EVIDENCE", "05 / MISSING EVIDENCE"),
        ("ACCELERATION_FLAG", "06 / ACCELERATION FLAG"),
    ]
    for i,(cls,title) in enumerate(specs):
        x,y=pos[i]
        rec=look[cls]
        box(x,y,835 if i<4 else 570,220 if i<4 else 210,cls,title,rec)
    missing_extra=next((r for r in rows if r["toy_splicing_delta"] is None),None)
    if missing_extra:
        x,y=pos[6];box(x,y,530,210,"INCOMPLETE_EVIDENCE","07 / NULL IS NOT ZERO",missing_extra)
    parts.extend([
        '<text x="105" y="1017" font-family="DejaVu Sans, Arial" font-size="21" fill="#687179">Illustrative thresholds only  •  No pathogenicity, mechanism, or clinical probability can be inferred.</text>',
        '</svg>',
    ])
    return "\n".join(parts).encode("utf-8")


def render_html(report:dict[str,Any]) -> bytes:
    esc=html.escape
    data=[]
    for i,r in enumerate(report["case_rows"]):
        cls=esc(r["evidence_class"])
        ca="null" if r["toy_phyloP_like"] is None else f'{r["toy_phyloP_like"]:+.2f}'
        mb="null" if r["toy_splicing_delta"] is None else f'{r["toy_splicing_delta"]:+.2f}'
        data.append(
            f'<tr data-kind="{cls}"><td>{i+1}</td><td><code>{esc(r["variant_id"])}</code></td>'
            f'<td>{ca}</td><td>{mb}</td><td><strong>{esc(r["class_label"])}</strong></td>'
            f'<td>{esc(r["next_research_question"])}</td></tr>'
        )
    header='''<!doctype html><html lang="zh-Hant"><head><meta charset="utf-8"><meta name="viewport" content="width=device-width, initial-scale=1"><title>Day03 | Two complementary lenses</title>
<style>body{margin:0;background:#E5DEDA;color:#394249;font-family:system-ui,sans-serif}main{max-width:1280px;margin:40px auto;background:#fffaf8;padding:45px;border-radius:24px;box-shadow:0 10px 30px #5a4d4d16}h1{font-size:2.1rem;margin:0}.subtitle{color:#706a70}.warning{padding:18px;margin:24px 0;border-radius:12px;background:#f6eae8;color:#773f4a;font-weight:650}button{border:1px solid #b6adb0;border-radius:18px;padding:9px 14px;margin:4px;background:white;color:#3b4c54;cursor:pointer}button:focus-visible{outline:3px solid #548b95}table{border-collapse:collapse;width:100%;font-size:15px}th,td{text-align:left;border-bottom:1px solid #e4dedb;padding:12px;vertical-align:top}th{background:#ede6e3}code{white-space:nowrap}.note{font-size:14px;color:#6b7178;margin-top:24px}@media(max-width:800px){main{padding:15px;margin:8px}table{display:block;overflow-x:auto}}</style></head><body><main>
<h1>兩個偵探,兩種研究線索</h1><p class="subtitle">Day 03 • Evolutionary constraint × Molecular prediction • Python OFFLINE</p>
<div class="warning">SYNTHETIC EDUCATIONAL DEMO:所有座標與分數為人工練習;沒有 AlphaGenome、PhyloP 或臨床結果。</div>
<p>篩選資料狀態:<button type="button" data-filter="ALL">全部</button><button type="button" data-filter="CONSERVATION_ONLY">保守性線索</button><button type="button" data-filter="MOLECULAR_ONLY">分子線索</button><button type="button" data-filter="INCOMPLETE_EVIDENCE">資料缺失</button></p>
<table><thead><tr><th>#</th><th>人工變異</th><th>phyloP-like</th><th>splice Δ</th><th>教學分類</th><th>下一個研究問題</th></tr></thead><tbody>'''
    footer='''</tbody></table><p class="note">注意:phyloP-like 正/負代理值、分子差分與分類閾值均為人工設定;特徵不一致不等於臨床證據互相矛盾。空白為 null,不可當作零。</p>
</main><script>document.querySelectorAll("button[data-filter]").forEach(button=>button.addEventListener("click",()=>{const f=button.dataset.filter;document.querySelectorAll("tbody tr").forEach(row=>{row.hidden=!(f==="ALL"||row.dataset.kind===f)}); }));</script></body></html>'''
    return (header+"\n"+"\n".join(data)+"\n"+footer+"\n").encode("utf-8")


def questions_md(report: dict[str,Any]) -> bytes:
    lines=[
        "# Day 03|兩種線索的研究問題卡(人工示範)", "",
        "> SYNTHETIC EDUCATIONAL DEMO|不是官方 PhyloP、AlphaGenome、AVI 或臨床分數。", "",
        "## 每筆人工資料要問什麼?", "",
    ]
    for v in report["case_rows"]:
        lines.append(f'- **`{v["variant_id"]}`**|{v["class_label"]}:{v["next_research_question"]}')
    lines += [
        "", "## 給研究者的五個問題", "",
        "1. 演化保守性的物種比對、缺口、基因組版本是什麼?",
        "2. 分子預測對應哪個 biosample、哪個模態與哪種單位?",
        "3. 有沒有缺失資料?是否把 null 誤寫成 0.0?",
        "4. 兩種線索不同時,有沒有另一種可解釋的機制與獨立驗證?",
        "5. 這些是否僅是模型或合成資料,而非濕實驗及臨床結論?",
        "", "人工示範不使用病患資料、不呼叫外部 API。", "",
    ]
    return "\n".join(lines).encode("utf-8")


def render_outputs(report: dict[str,Any]) -> dict[str,bytes]:
    return {
        OUTPUT_FILES[0]: dumps_json(report),
        OUTPUT_FILES[1]: csv_bytes(report["case_rows"], CSV_COLUMNS),
        OUTPUT_FILES[2]: draw_svg(report),
        OUTPUT_FILES[3]: render_html(report),
        OUTPUT_FILES[4]: questions_md(report),
    }


def run(fixture_path: Path, out_dir: Path, *, mode: str="offline") -> dict[str,Any]:
    if mode != "offline":
        raise PermissionError("LIVE mode is intentionally disabled")
    if out_dir.exists():
        raise FileExistsError("Refusing to overwrite existing output directory")
    fixture_raw=fixture_path.read_bytes()
    data=json.loads(fixture_raw.decode("utf-8"),parse_constant=lambda _: (_ for _ in ()).throw(ValueError("NaN/Inf not allowed")))
    report=build_report(data,fixture_name=fixture_path.name,fixture_sha256=sha256_bytes(fixture_raw))
    result=render_outputs(report)
    manifest={
        "status":"PASS", "mode":"OFFLINE_ONLY", "source_name":fixture_path.name,
        "source_sha256":report["fixture_sha256"],
        "artifact_count":len(result),
        "artifacts_sha256":{name:sha256_bytes(b) for name,b in sorted(result.items())},
        "manifest_is_signed":False,
        "real_api_calls_this_run":0,
    }
    out_dir.mkdir(parents=True,exist_ok=False)
    for name,contents in result.items():
        (out_dir/name).write_bytes(contents)
    (out_dir/"day03_manifest.json").write_bytes(dumps_json(manifest))
    return {
        "status":"PASS", "mode":"OFFLINE_ONLY",
        "variant_count":report["variant_count"],
        "classification_counts":report["classification_counts"],
        "missing_conservation_count":report["missing_conservation_count"],
        "missing_molecular_count":report["missing_molecular_count"],
        "artifact_count":len(result),
        "real_api_calls_this_run":0,
        "output_dir":str(out_dir),
    }


def verify(fixture_path: Path, out_dir: Path, *, mode: str="offline") -> dict[str,Any]:
    if mode != "offline":
        raise PermissionError("LIVE mode is intentionally disabled")
    manifest=json.loads((out_dir/"day03_manifest.json").read_text(encoding="utf-8"))
    if manifest.get("mode")!="OFFLINE_ONLY" or manifest.get("status")!="PASS" or manifest.get("manifest_is_signed") is not False:
        raise ValueError("Invalid unsigned offline manifest")
    if manifest.get("source_name")!=fixture_path.name or manifest.get("source_sha256")!=sha256_file(fixture_path):
        raise ValueError("Source fixture fingerprint mismatch")
    expected_names=set(OUTPUT_FILES)
    checksums=manifest.get("artifacts_sha256")
    if not isinstance(checksums,dict) or set(checksums)!=expected_names or manifest.get("artifact_count")!=len(expected_names):
        raise ValueError("Artifact list mismatch")
    actual_names={p.name for p in out_dir.iterdir() if p.is_file()}
    if actual_names!=expected_names|{"day03_manifest.json"}:
        raise ValueError("Unexpected or missing output artifacts")
    for name in OUTPUT_FILES:
        if sha256_file(out_dir/name)!=checksums[name]:
            raise ValueError(f"Artifact altered: {name}")
    data=json.loads(fixture_path.read_text(encoding="utf-8"))
    canonical=render_outputs(build_report(data,fixture_name=fixture_path.name,fixture_sha256=sha256_file(fixture_path)))
    for name in OUTPUT_FILES:
        if (out_dir/name).read_bytes()!=canonical[name]:
            raise ValueError(f"Output diverges from recomputed teaching report: {name}")
    return {"status":"PASS","checksums":"MATCH","files_verified":len(expected_names),"real_api_calls_this_run":0,"manifest_is_signed":False}


def main(argv: list[str]|None=None) -> None:
    parser=argparse.ArgumentParser(description="Day03 two-lenses synthetic Python lab (offline only)")
    commands=parser.add_subparsers(dest="command",required=True)
    for command in ("run","verify"):
        sub=commands.add_parser(command)
        sub.add_argument("--mode",choices=["offline","live"],default="offline")
        sub.add_argument("--fixture",type=Path,default=Path("day03_synthetic_two_lenses.json"))
        sub.add_argument("--output-dir",type=Path,default=Path("day03_output"))
    args=parser.parse_args(argv)
    fn=run if args.command=="run" else verify
    print(json.dumps(fn(args.fixture,args.output_dir,mode=args.mode),ensure_ascii=False,sort_keys=True))

if __name__=="__main__":
    main()
下載作者審稿包 ZIP 後,請在 WSL Ubuntu Bash 終端機執行:
cd /mnt/c/Users/user/Downloads
mkdir -p ~/alphagenome-day03-qa
python3.12 -m zipfile -e AlphaGenome_Day03_Conservation_Molecular_API_Bridge_Author_Review_Pack.zip ~/alphagenome-day03-qa
cd ~/alphagenome-day03-qa
python3.12 -B -m unittest -v test_day03_offline_two_lenses_lab
python3.12 -B day03_offline_two_lenses_lab.py run --mode offline --fixture day03_synthetic_two_lenses.json --output-dir day03_output
python3.12 -B day03_offline_two_lenses_lab.py verify --fixture day03_synthetic_two_lenses.json --output-dir day03_output
執行成功後,終端機的摘要會包含:
{
  "status": "PASS",
  "mode": "OFFLINE_ONLY",
  "variant_count": 7,
  "classification_counts": {
    "ACCELERATION_FLAG": 1,
    "BOTH_SUGGESTIVE": 1,
    "CONSERVATION_ONLY": 1,
    "INCOMPLETE_EVIDENCE": 2,
    "MOLECULAR_ONLY": 1,
    "NEITHER_TOY_SIGNAL": 1
  },
  "missing_conservation_count": 1,
  "missing_molecular_count": 1,
  "artifact_count": 5,
  "real_api_calls_this_run": 0
}
這是實際 stdout 中關鍵欄位的節錄;完整輸出還有本機 output_dir。驗證會回傳 checksums=MATCH、files_verified=5 和 manifest_is_signed=false。也就是說,這份 SHA-256 清單有助於本地偵測修改,但不是獨立第三方簽署的資料來源證明。
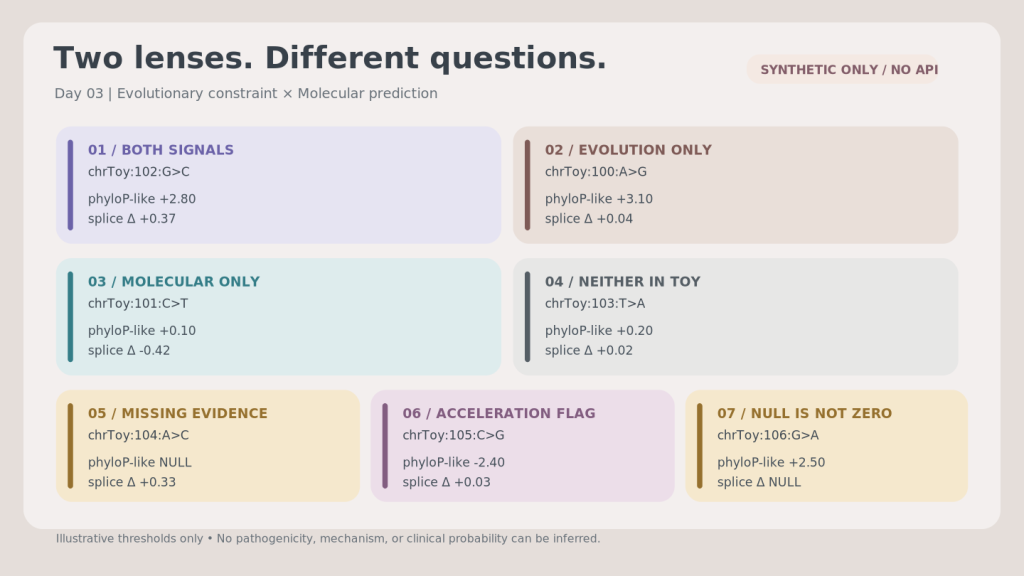
null 當作缺失資料而非 0.0。作者既有內容:「Face ID 與舊手機」和 Google AI Studio 的逆向拆解方法,是作者原本想用來引起初學者好奇心的敘事。原文裡若保留特定 AUPRC、罕病排名、SHAP 百分比或「Production Ready」字樣,仍須逐項核對論文條件與實際執行證據;本次範例沒有驗證那些結果。
官方背景: UCSC PhyloP 是跨物種演化速率訊號;CADD 提供整合註解的相對排序,PHRED-like 不是致病機率;AlphaGenome 可從序列預測多種分子讀出,但不能以單一分數直接做臨床診斷。
本篇軟體: 所有座標和數值皆屬合成資料,只有七筆教學輸入;不下載真實 phyloP、CADD 或 AlphaGenome 回應,不使用患者資料,不產生醫療建議或自行執行實驗。程式測試僅證明它在人工資料上的軟體行為。
明天 Day 04,我們將從這兩種互補線索,走進 AlphaGenome Atlas 的 In Silico 預先計算:為什麼同一個 DNA 變異可以先在 Variant View 看總體預測,再用 Locus View 觀察區間軌跡?也會第一次把 Google AI Studio 生成的畫面,和 Python 的資料合約正式對照。


 iThome鐵人賽
 看影片追技術